Model comparison
Metered cost per task set, indexed to Claude Opus 4.8
About 60% lower cost with GLM-5.2, with similar judged quality (4.2 vs. 4.3 out of 5). Both passed 6 of 6 automated suites.
Momento Benchmarks
We test models and harnesses on real tasks from production repositories. Every run is metered for cost and scored by an independent judge panel.
Explore mo evalMetered cost and judged quality
Benchmark Results
Metered cost per task set, indexed to Claude Opus 4.8
About 60% lower cost with GLM-5.2, with similar judged quality (4.2 vs. 4.3 out of 5). Both passed 6 of 6 automated suites.
mo vs. Claude Code · Same task and test criteria
Model comparison from six production repositories, scored by an independent multi-model judge panel.
Watch it happen: one task, same prompt, same hidden test gate, captured from a real run and shown accelerated. mo phase-shifts (Opus plans, GLM-5.2 builds) and lands the same result 2.5× cheaper, 2.6× faster.
How we test
Each benchmark holds everything constant except the one part being tested. The same tasks run repeatedly, and the results are compared side by side.
Tasks from production repositories rather than public benchmark sets. Each task has a hidden test gate the agent never sees.
Runs the same tasks, harness, skills, and tools. Only one part changes, such as the model.
Every task runs several times, so a single lucky or unlucky run can't decide the result.
Use mo eval to compare coding-agent setups on your own tasks, with metered cost, judged quality, and speed.
Seattle Systems talk
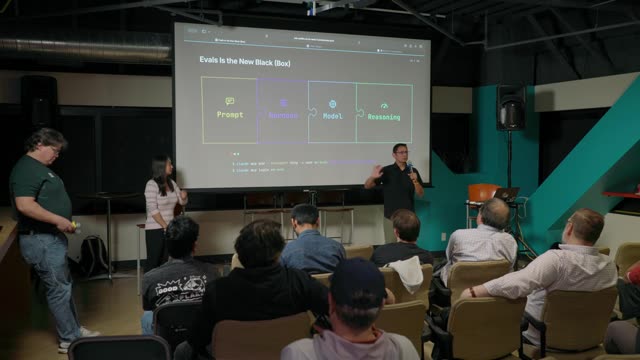
Khawaja Shams and Daniela Miao discuss what it takes to evaluate coding agents and why the whole setup matters.
View the talk and captions